Scaling to 16 GPUs: DeepSeek v3.2 and Qwen3.5 at home
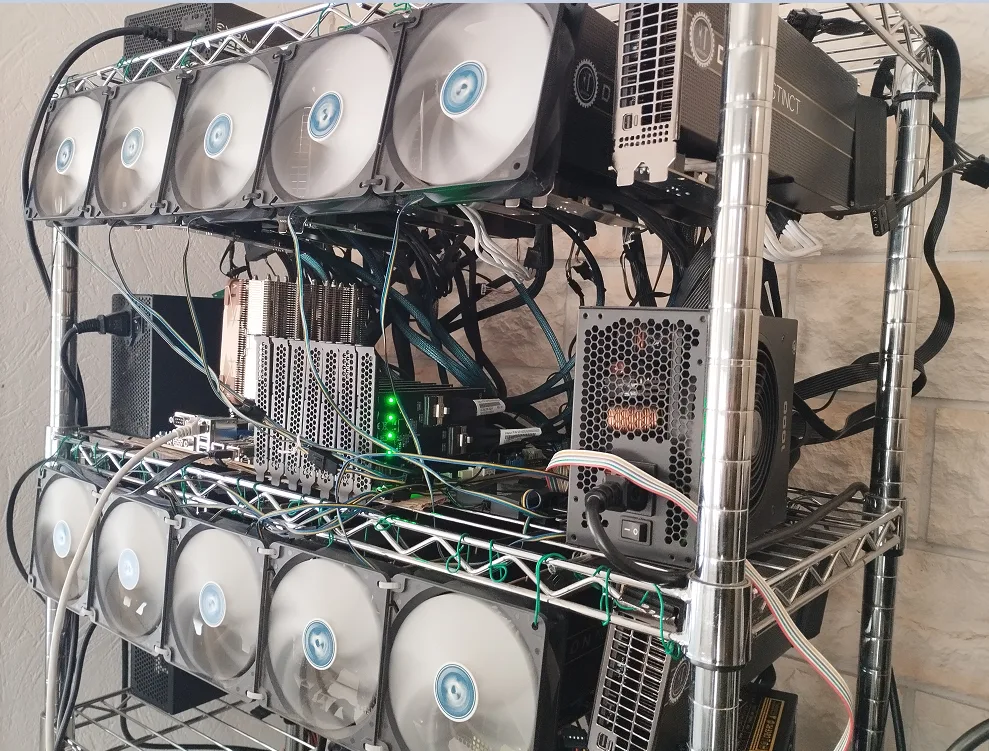
- 16× AMD MI50 32GB - 512 GB of VRAM
- Total cost: ~€5.6k (~€150/card at the time)
- Qwen3.5 397B: 32 tokens/s generation
- DeepSeek v3.2: 10 tokens/s generation
- 550 W idle / 2,400 W peak
- Honest correction: the real measured prompt processing is ~56 tokens/s (the speed shown in vLLM logs was misleading)
After the 8-GPU rig, the logical next step: double it. Twice the VRAM, and above all access to another category of models - the ones that simply do not fit in 256 GB.
With 512 GB of VRAM, DeepSeek v3.2 in 4-bit runs at 10 tokens/s generation. And when Qwen3.5 397B came out, I got it running at 32 tokens/s - a nearly 400-billion-parameter model, at home, at a perfectly usable everyday speed.
One important note, which I added to all my posts: at first I reused the prompt processing figure straight from the vLLM logs (2,000 tokens/s). Measuring it end to end myself, the real value is much lower. Let me say it plainly: the numbers tools display are not always real numbers. Measure.
A goal, not a collection
I do not collect GPUs. My goal is clear: be ready for local AGI without spending more than $300k. I am not a giant lab with an infinite budget - just a determined builder, and if I can do it, many others can too. That is also why I publish everything: every rig has its own detailed, open guide.
What the community asked me
The DeepSeek post got more than 450 upvotes and 245 comments - by far the most popular of the series. The questions that keep coming:
- "What's the total cost?"
- Around €5.6k all in, with cards at ~€150 at the time. Those days are gone: MI50 prices have risen a lot since. The same build would cost clearly more today.
- "2,400 W at home - how is that even possible?"
- In Europe, each 1,600 W power supply sits on its own circuit. Before pulling anything, I mapped out the breakers in the house to know exactly what each circuit can take. Do the same - and get help if you are not sure.
- "Why local, when the cloud looks cheaper?"
- For autonomy, independence, security and privacy, not for the token cost. And because I want to know today whether second-hand hardware can run tomorrow's models at home. Verdict: yes.
- "What about stability at long context?"
- In my tests DeepSeek v3.2 produced garbage beyond ~18,000 tokens of context. MiniMax and GLM stayed stable at long context - those are the ones I use for coding agents. (UPDATE: since v0.17 of my vllm-gfx906-mobydick fork, the DeepSeek v3.2 coherence issues have been fixed and it stays stable across its entire context.)